A Third of New Web Pages Are Written With AI: Filtering Synthetic Content Out of Scraped Datasets
Pew estimates 35% of new dated web pages show AI authorship. Here is how to…
Measuring AI Search Answers Without Fooling Yourself: Sampling, Drift and Evidence Trails for LLM-Answer Data Collection
How to collect AI search answer data you can trust: repeated runs, fixed settings, follow-up…
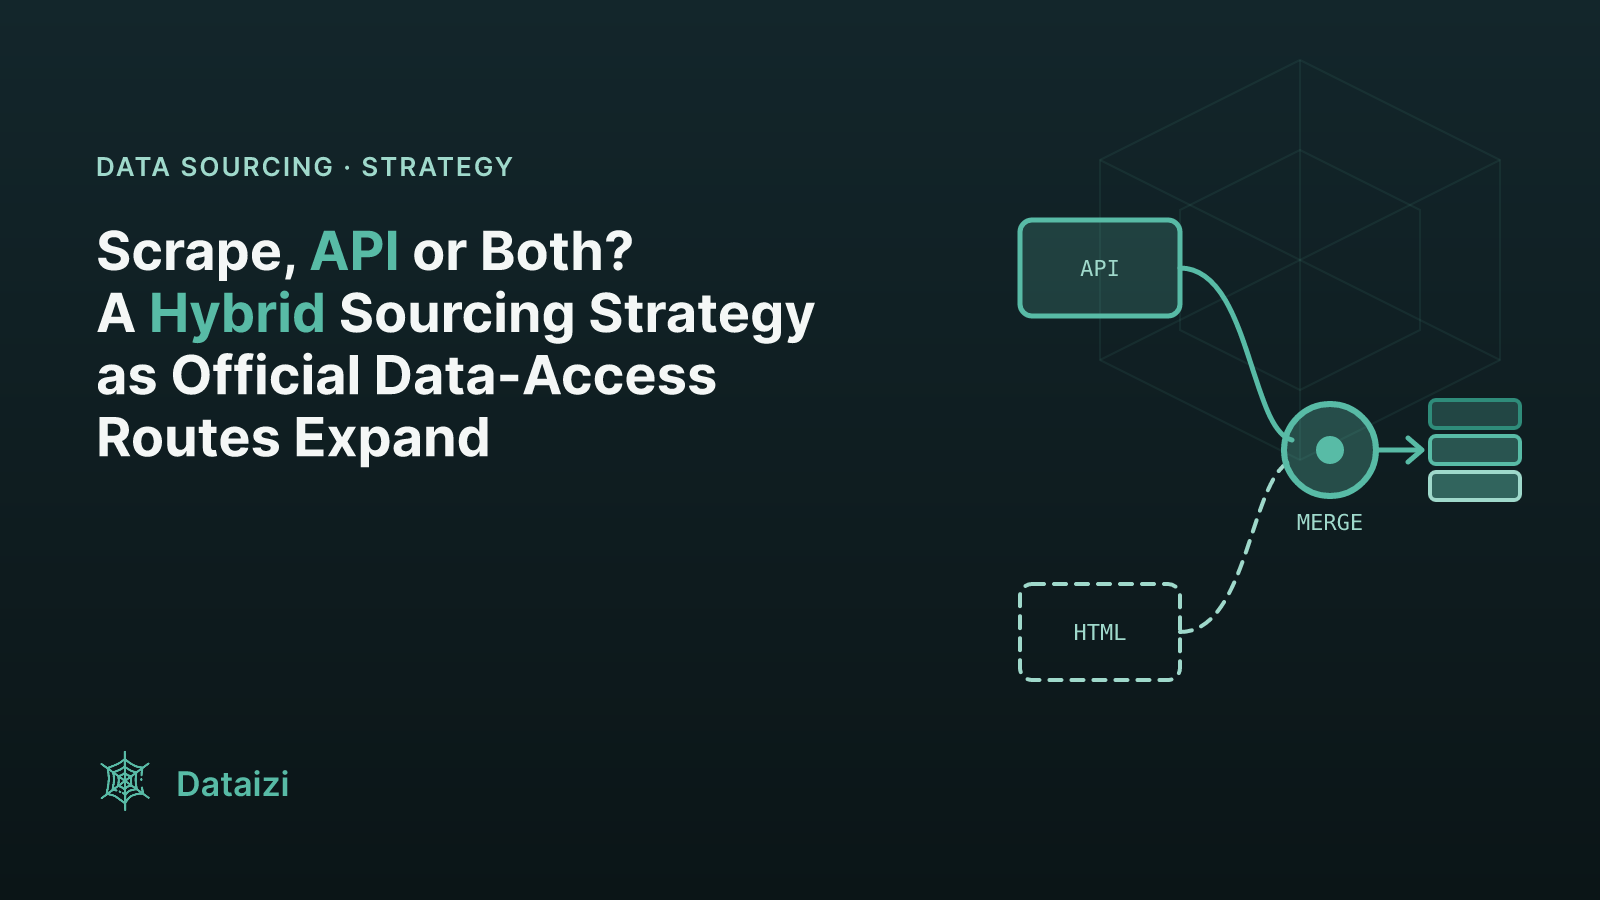
Scrape, API or Both? A Hybrid Sourcing Strategy as Official Data-Access Routes Expand
A hybrid data sourcing strategy routes each field to the cheapest lawful access route: official…
Search API, Crawl API or Your Own Fleet? A Decision Guide to Web Data Access for AI Agents
Search APIs, crawl APIs and your own scraping fleet solve different problems for AI agents.…
Incremental Crawling Done Right: Change Detection, Deduplication and Entity Resolution for Scraped Data at Scale
How to re-crawl only what changed, keep duplicates out of your warehouse, and avoid the…
Turning Raw Data Into Actionable Insights: The Power of Managed Datasets
Introduction Raw data is everywhere — but making it useful takes time, infrastructure, and expertise.…